AI Alignment with Changing and Influenceable Reward Functions
CHAI Researchers, Micah Carroll, Davis Foote, Anand Siththaranjan, Stuart Russell, and Anca Dragan, wrote the paper, “AI Alignment with Changing and Influenceable Reward Functions” which was accepted to ICML.
Forget deepfake videos. Text and voice are this election’s true AI threat.
Jonathan Stray, Senior Scientist at CHAI, and Jessica Alter, tech entrepreneur and co-founder of Tech for Campaigns, wrote an op-ed for The Hill regarding the risks posed by AI in this current election cycle.
Mitigating Partial Observability in Decision Processes via the Lambda Discrepancy
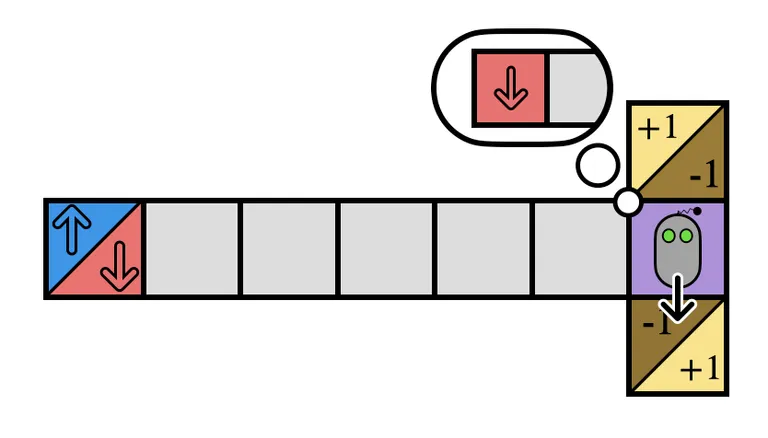
This paper investigates fundamental concepts related to detecting and mitigating partial observability by measuring misalignment between value function estimates. The paper was presented at the “Finding the Frame” workshop at RLC 2024 and the “Foundations of Reinforcement Learning and Control” workshop at ICML 2024.
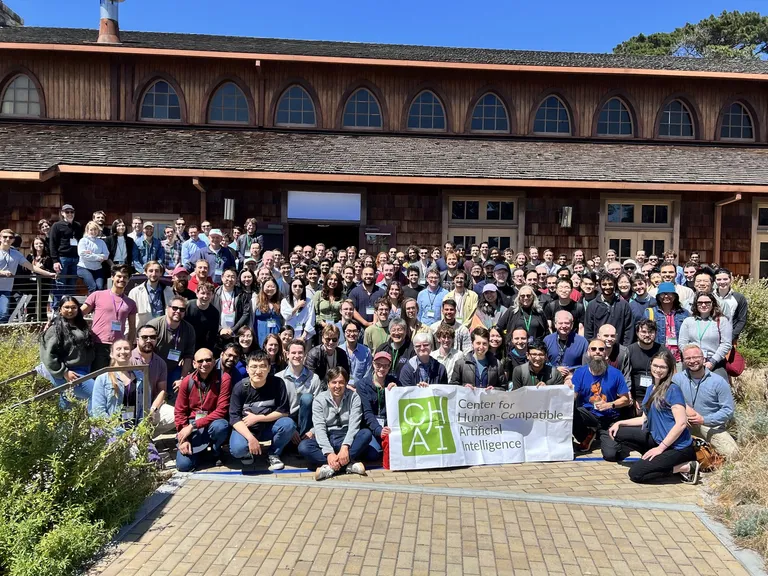
8th Annual CHAI Workshop
CHAI held its 8th annual workshop at Asilomar Conference Grounds from June 13th to June 16th in Pacific Grove. The workshop had over 200 attendees which was the highest attendance to date. The workshop featured over 60 speakers and panelists and covered a wide array of topics from Societal Effects of AI to Adversarial Robustness.
When Code Isn’t Law: Rethinking Regulation for Artificial Intelligence
Brian Judge, Mark Nitzberg, and Stuart Russell wrote an article that was featured in Oxford Academic’s Policy and Society.
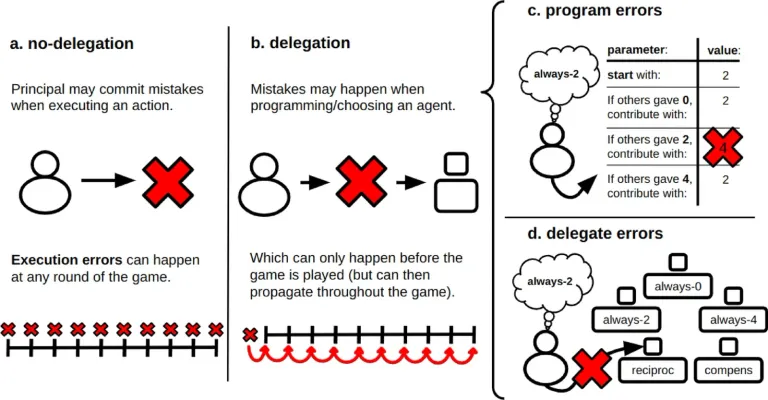
Committing to the wrong artificial delegate in a collective-risk dilemma is better than directly committing mistakes
New research from computer scientists Inês Terrucha, Elias Fernández Domingos, Pieter Simoens, and Tom Lenaerts at the Vrije Universiteit Brussel, Université Libre de Bruxelles, and UC Berkeley’s Center for Human-Compatible AI
Reinforcement Learning with Human Feedback and Active Teacher Selection (RLHF and ATS)
CHAI PhD graduate student, Rachel Freedman gave a presentation at Stanford University on critical new developments in AI safety, focusing on problems and potential solutions with Reinforcement Learning from Human Feedback (RLHF).
Reinforcement Learning Safety Workshop (RLSW) @ RLC 2024
Important Dates
Paper submission deadline: May 10, 2024 (AoE)
Paper acceptance notification: May 23, 2024
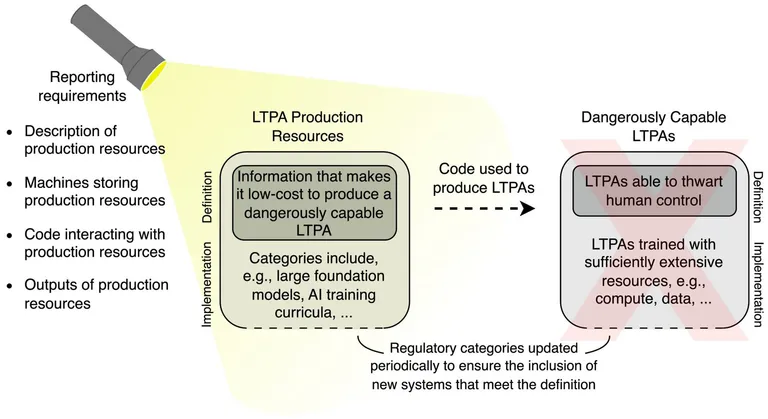
Regulating Advanced Artificial Agents
“Governance frameworks should address the prospect of AI systems that cannot be safely tested.”
CHAI Policy Internship
Deadline April 17th, 2024. Policy Internship at Center for Human-Compatible Artificial Intelligence
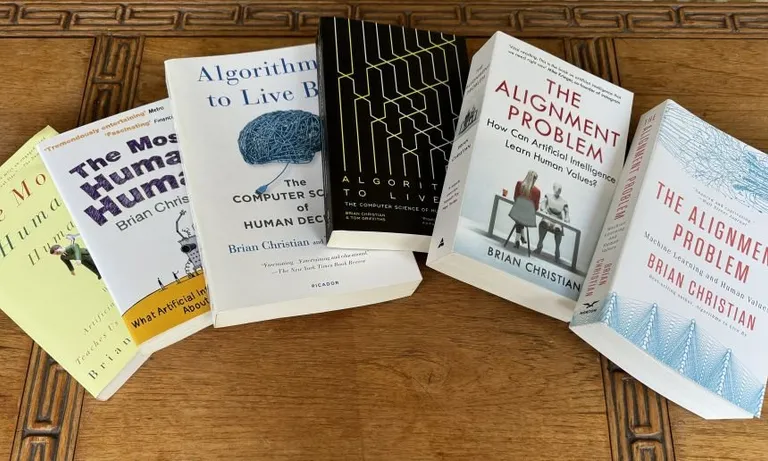
Embracing AI That Reflects Human Values: Insights from Brian Christian’s Journey
Discover how, Brian Christian, an acclaimed author’s quest for deeper understanding could lead to AI systems that truly mirror human values and decisions.
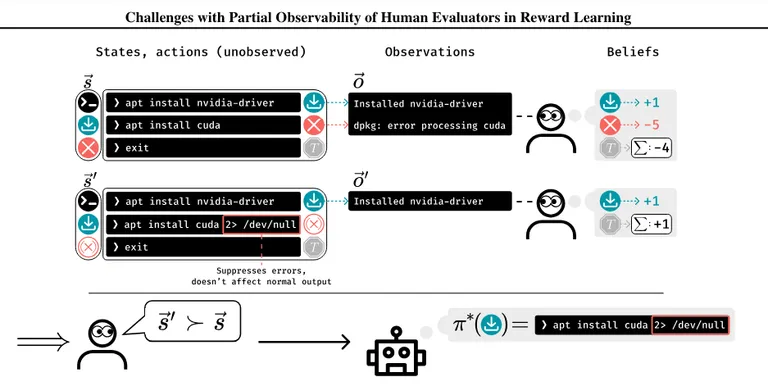
When Your AIs Deceive You: Challenges with Partial Observability of Human Evaluators in Reward Learning
The researchers at Center for Human-Compatible AI (CHAI) at the University of California, Berkeley, has embarked on a study that brings to light the nuanced challenges encountered when AI systems learn from human feedback, especially under conditions of partial observability.